2022年12月31日 星期六

openai artwork with R

使用R進行 openai 藝術創作


https://youtu.be/izha883dq-E

【謝謝各位大大按 讚、訂閱、開啟小鈴鐺】


OpenAI [https://openai.com/] 相繼推出 GPT-3 語言模型與 DALL-E2 AI 產生器, 使用者只要輸入文字, 即可以產生的超現實主義圖片, 參考圖1所示, 本篇文章示範 R 與 openai 套件的應用.

圖1 太空人騎馬照


步驟1 建立 OpenAI 帳號

開啟 OpenAI 網頁的API連結 [https://openai.com/api/], 參考圖2. 如果第1次登入, 選取右側 SIGN UP按鈕, 新增帳號. 如果已經有帳號, 直接選取左側 LOG IN 按鈕


圖2 OpenAI API 畫面


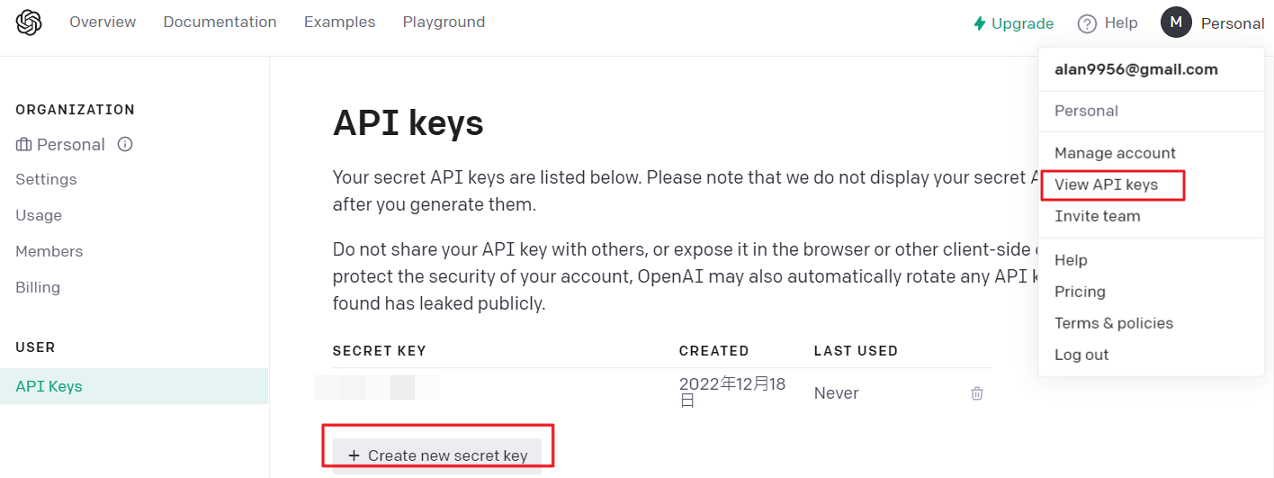
登入成功後, 右側 [M Personal] \ View API Keys \ + Create new secret key, 結果會顯示 API Key, 記得按下 [Copy] 按鈕, 後續須複製到 R 程式碼.

圖3 API Key 畫面


右側 [M Personal] \ Manage account, 結果會顯示目前帳戶餘額, 預設前3個月會有 USD.18元可使用. 注意本項服務不是完全免費. Pricing 網頁有提供價格訊息 [https://openai.com/api/pricing/].

圖4 Manage accoun 畫面


步驟2 安裝 openai 套件


步驟3 完整 R 程式碼

# Title    : openai artwork with R
# Author   : Ming-Chang Lee
# Email    : alan9956@gmail.com
# RWEPA    : http://rwepa.blogspot.tw/
# GitHub   : https://github.com/rwepa
# Encoding : UTF-8

# 步驟1 建立 OpenAI 帳號
# https://openai.com/api/

# 步驟2 安裝 openai 套件
# https://cran.r-project.org/web/packages/openai/index.html
install.packages("openai")

# 輸入步驟1所建立的 API key
Sys.setenv(
  OPENAI_API_KEY = '輸入步驟1所建立的 API key'
)

# 載入 openai 套件
library(openai)

# 建立完成物件
create_completion(
  model = "ada",
  prompt = "Generate a question and an answer"
)

# 範例1 太空人騎馬照
create_image("An astronaut riding a horse in a photorealistic style")

# 上述程式碼會建立連結網址, 參考圖5.

圖5 create_image 畫面


# 將 https:// 開始的所有字元複製到瀏覽器, 即可呈現圖1之結果.


# 範例2 山谷飛兔照
create_image("flying rabbit in the valley")

圖6 山谷飛兔照


# HAPPY NEW YEAR 2023

2022年10月22日 星期六

shiny for Python (Python 使用 shiny 模組教學)

Python 程式使用 shiny 模組執行結果:


R語言的 shiny 套件可以建立跨平台的互動式網頁,今年(2022)RStudio 研討會宣佈 shiny for Python, 表示在 Python 環境亦可執行 shiny 建立互動式網頁。

PyPI shiny: https://pypi.org/project/shiny/


Youtube 說明:


https://youtu.be/s2fgEAa6lq0

【謝謝各位大大幫忙按 訂閱、開啟小鈴鐺】


PDF講義大綱:

  1. RWEPA 簡介
  2. 資料分析架構 --> APC方法
  3. 資料分析與視覺化應用
  4. shiny 簡介
  5. shiny for Python 實作篇1 - my_app
  6. shiny for Python 實作篇2 – 01_hello
  7. 結論

https://github.com/rwepa/shiny_python/blob/main/shiny_python_tutorial.pdf


Python 程式:

https://github.com/rwepa/shiny_python/blob/main/pyshiny_01_hello.py


檔案架構:

  • shiny 一般以資料夾方式儲存, 本例為 pyshiny_01_hello 資料夾
  • Python 主程式: pyshiny_01_hello.py, 程式名稱不一定是 app.py
  • Python 主程式路徑: D:\shinydemo\pyshiny_01_hello\pyshiny_01_hello.py


執行方式:

Windows 開啟命令提示字元,輸入以下內容:

  • d:
  • cd shinydemo
  • shiny run --reload pyshiny_01_hello/pyshiny_01_hello.py
  • 瀏覽器輸入 http://localhost:8000/


參考資料:

  1. RWEPA: http://rwepa.blogspot.com/
  2. RWEPA shiny: http://rwepa.blogspot.com/search?q=shiny
  3. Shiny for R: https://shiny.rstudio.com/
  4. Shiny for Python: https://shiny.rstudio.com/py/
  5. shiny for Python 實作篇2 – 01_hello 程式碼: https://github.com/rwepa/shiny_python

# end

2022年8月28日 星期日

Python 連接 Microsoft SQL Server

Python 連接 Microsoft SQL Server (Windows 10)

感謝 Jian-Guo 提供問題.


系統:

Windows 10, Microsoft SQL Server 2019 Developer Edition, Python 3.9.12

目標:

在 Windows 系統中, 希望使用 Python - sqlalchemy 模組, 連結 Micorosft SQL Server.

方法:

步驟1: 下載 Microsoft SQL Server

首先至 Microsoft SQL Server 的網頁下載並安裝 SQL Server [https://www.microsoft.com/en-us/sql-server/sql-server-downloads], 參考下圖下載 SQL Server 2019 Developer.


參考下圖 SQL Server 安裝執行畫面.


如果想使用 R 連接 Microsoft SQL Server, 請參考 [http://rwepa.blogspot.com/2013/08/rodbc-sql-server.html].

步驟2: 下載並安裝 sqlalchemy 模組

方法1: conda install -c anaconda sqlalchemy
方法2: pip install sqlalchemy

步驟3: 使用 sqlalchemy 模組連結 Microsoft SQL Server

# sqlalchemy_sql.py
import sqlalchemy
print(sqlalchemy.__version__) # 1.4.32

from sqlalchemy import create_engine
import pandas as pd

Server = 'localhost'
Database = 'Northwind'
Driver = 'ODBC Driver 17 for SQL Server'
Database_Con = f'mssql://@{Server}/{Database}?driver={Driver}'

engine = create_engine(Database_Con)
con = engine.connect()
con

df = pd.read_sql_query('SELECT * FROM Employees', con)
df.iloc[0:3,0:4]
###

執行畫面:


# end

2022年7月31日 星期日

Standard Deviation in Python, R


標準差之計算在 Python, R 結果都相同嗎?

感謝 Pei-Chun 提供 Python 問題.

標準差

統計學的標準差(Standard Deviation, SD)可以區分為母體標準差與樣本標準差, 符號之說明如下:

σ: 母體標準差, N: 母體個數, μ:  母體平均值

s: 樣本標準差, n: 樣本個數, x_bar: 樣本平均值

母體標準差與樣本標準差之計算公式:


公式法

考慮資料集為 {1,2,3,4,5}, μ = (1+2+3+4+5)/5=3, 使用公式法計算結果:

母體標準差 σ =(((1-3)^2+...+(5-3)^2)/5)^0.5=1.414214 (分母為5)

樣本標準差 σ =(((1-3)^2+...+(5-3)^2)/4)^0.5=1.581139 (分母為4)

Python-numpy 模組-不含NA值

使用 numpy.std 函數可以計算標準差, 分母預設值為樣本數 n, 其中參數 ddof(Means Delta Degrees of Freedom) 的預設值為 ddof=0, 如果設定 ddof=1, 則分母為 n-1, 詳細參考線上說明 [LINK].


Python-pandas 模組-不含NA值

使用 pandas.describe 函數以計算標準差, 其預設值為 n-1. 

使用 df.describe().iloc[2,0] 取出 std 值, 另外也可以使用 df.describe().loc['std'] 取出 std值.


Python-numpy 模組-有NA值

上述討論都沒有NA值的情形, 如果資料包括NA值時, 其計算結果為 nan, 使用 numpy.nanstd 函數可以忽略 NA值並計算標準差.


Python-pandas 模組-有NA值

使用 pandas.describe 函數以計算標準差, 其預設值為 n-1, 且會忽略NA值並計算標準差, 此特性須特別注意.


R-不含NA值

使用 sd {stats} 函數可計算標準差. stats 為R內建30個標準套件之一, 啟動R時, 已經載入該套件. 計算結果分母採用 n-1.


R-有NA值

如果資料有NA值, 則 sd 計算結果為 NA. 

使用 na.rm = TRUE 參數可忽略NA值並計算標準差.


結論

使用 Python 與 R 語言須確認計算標準差之意義, 如果資料有NA值, 須特別小心處理.

# end

2022年7月2日 星期六

Python Orange-Associate Tutorial

主題: Python Orange - 關聯規則教學


本篇說明 Python 的 Orange 模組中,  外掛 Associate 的使用, 包括建立頻繁項目集與關聯規則.

感謝 Chen-Yao 提供此問題.


Youtube: 


Orange 3 特性:
University of Ljubljana, Slovenia, 10 October 1996
視覺化程式設計工具(Visual Programming Tools)
執行更加快速(C++)與視覺化操作
提供多種機器學習模組
開放原始碼與跨平台
適用於Python模組
資料預處理
模型訓練
部署

大綱:
1. Orange 3 簡介
2. Orange 3 安裝 
3. 安裝 Add-ons Associate
4. 案例示範 (技巧: Pivot Table 樞紐分析)
5. Q & A


Github資料:

資料集:
northwind_trans.csv

2022年6月17日 星期五

R-normalizePath Error - OneDrive/??

問題:

近日安裝 Windows 與 R之後會有以下 normalizePath 語法錯誤:


查詢發現電腦確實有以下之目錄 C:\Users\asus\OneDrive\文件, 因此最有可能原因是此路徑包括中文字型"文件", 因此R解析結果為錯誤??

使用 path.expand 函數亦是錯誤

> path.expand("~/")

[1] "C:/Users/asus/OneDrive/??/"


使用 normalizePath 函數也有錯誤

> normalizePath(path.expand("~/"))

[1] "C:\\Users\\asus\\OneDrive\\??\\"

Warning message:

In normalizePath(path.expand(path), winslash, mustWork) :

  path[1]="C:/Users/asus/OneDrive/??/": 檔案名稱、目錄名稱或磁碟區標籤語法錯誤。


方法:

步驟1. 先關閉 RStudio


步驟2. 新增系統變數

1. 程式集 \ 設定 \ 關於 \ 進階系統設定


2. 選取環境變數


3. 按 系統變數 \ 新增


4. 設定名稱與值, 依實際需求修改, 按確定.

變數名稱: HOME

變數值:     C:\Users\asus


步驟3. 重新開啟 RStudio 或重新啟動 Windows 結果為正確

> path.expand("~/")

[1] "C:/Users/asus/"

> normalizePath(path.expand("~/"))

[1] "C:\\Users\\asus"

# end

2022年5月29日 星期日

iPAS - Big Data Analyst - Free Course


iPAS - 巨量資料分析師認證 - 免費線上參考課程

講師:李明昌

考試網址:https://www.ipas.org.tw/bda/


巨量資料分析師-資料導向程式設計(一)

網址:https://collegeplus.itri.org.tw/course/1161

單元一:資料類型與物件

單元二:資料庫概念(含NoSQL)

單元三:資料匯入與匯出


巨量資料分析師-資料導向程式設計(二)

網址:https://collegeplus.itri.org.tw/course/1162

單元一:程式設計類型

單元二:自訂函數與控制敘述

單元三:程式除錯與效能提升方法


巨量資料分析師-資料處理與分析概論(一)

網址:https://collegeplus.itri.org.tw/course/1165

單元一:資料組織與清理(1)

單元二:資料組織與清理(2)

單元三:資料摘要與彙總(1)

單元四:資料摘要與彙總(2)

單元五:屬性轉換與萃取(1)

單元六 : 屬性轉換與萃取(2)

單元七 : 巨量資料處理概念(1)

單元八 : 巨量資料處理概念(2)


巨量資料分析師-資料處理與分析概論(二)

網址:https://collegeplus.itri.org.tw/course/1166

單元一:統計分析基礎(1)

單元二:統計分析基礎(2)

單元三:統計分析基礎(3)

單元四:探索式資料分析與非監督式學習(1)

單元五:探索式資料分析與非監督式學習(2)

單元六:線性模型與監督式學習(1)

單元七 : 線性模型與監督式學習(2)

# end